TL;DR: MemBlocks is a modular memory architecture for LLMs that lets users own their data, decide what the AI can see, and maintain isolated long-term memory across different domains of their lives, while minimizing token/context usage and keeping long-term memory quality high through agentic memory management. These independent, domain-scoped Blocks are each partitioned into structured sections to enable efficient, high-quality context retrieval. It’s built as a Python library with MCP integration, available on pip.
The problem
LLMs have no persistent memory. Most solutions dump everything into one undifferentiated store, producing a RAG system with retrieval noise, cross-domain leakage and zero user control.
Blocks
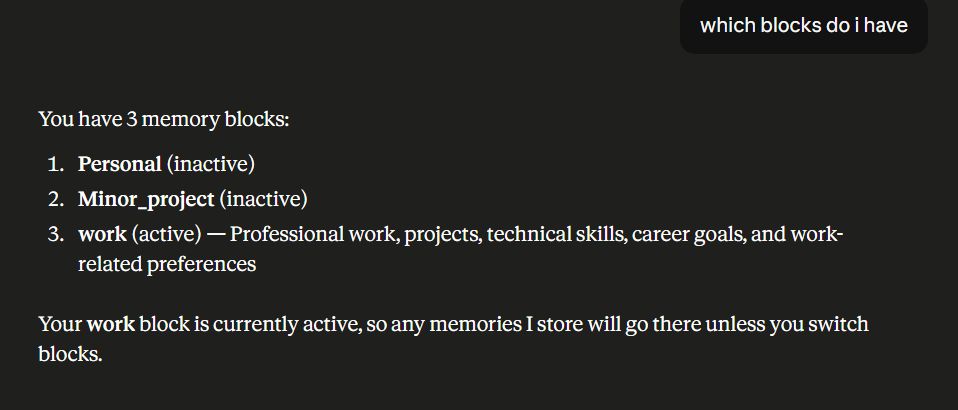
To solve this, MemBlocks organises memory into independent, attachable Blocks (or containers), each mapped to a distinct, user-defined domain (e.g. work, personal, academic). Within each Block, memory is split into three sections:
- Core memory: persistent facts, always in context
- Semantic memory: extracted knowledge with conflict-aware deduplication
- Recursive summary: compressed recent conversational state
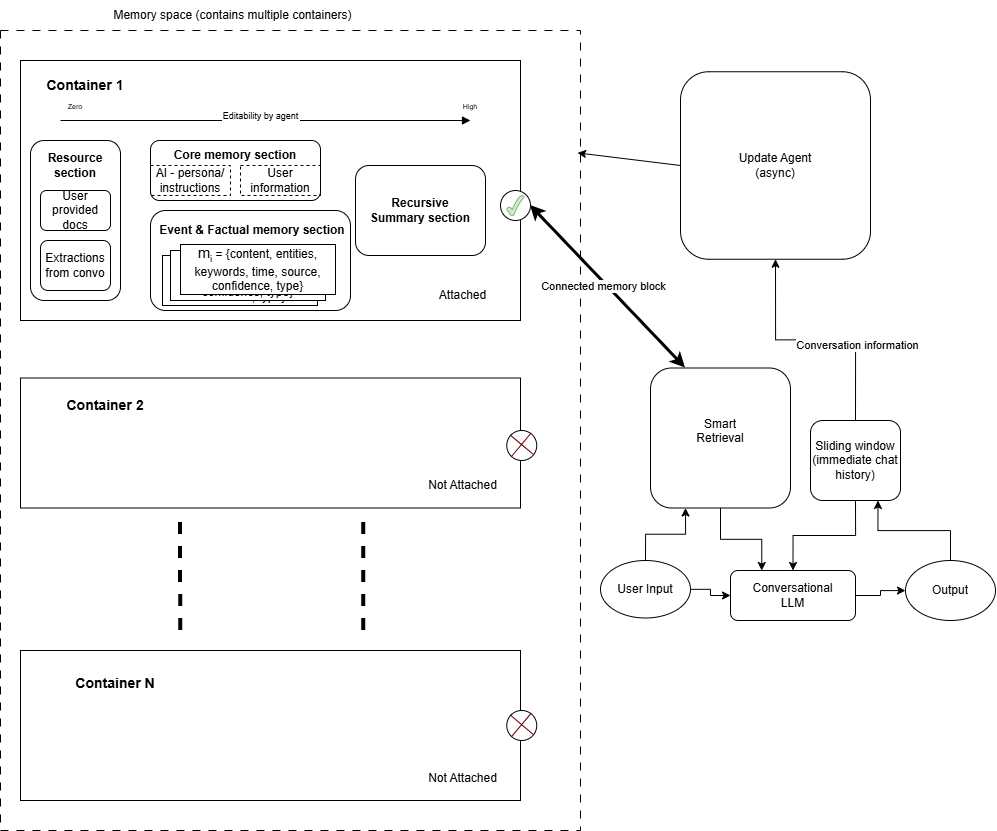
MemBlocks uses agentic memory management with three async parallel pipelines that handle extraction, conflict resolution and summary regeneration. It’s inspired by frameworks like MemGPT/Letta, Mem0, A-MEM and MIRIX, but with a deliberate focus on something most of these overlook: user-level control. You decide what each Block represents. You attach only what’s relevant to a conversation. You can separate your work life from your personal life from your research, and none of those domains can bleed into each other. Blocks can even be shared across multiple users, enabling collaborative memory spaces.
MCP integration
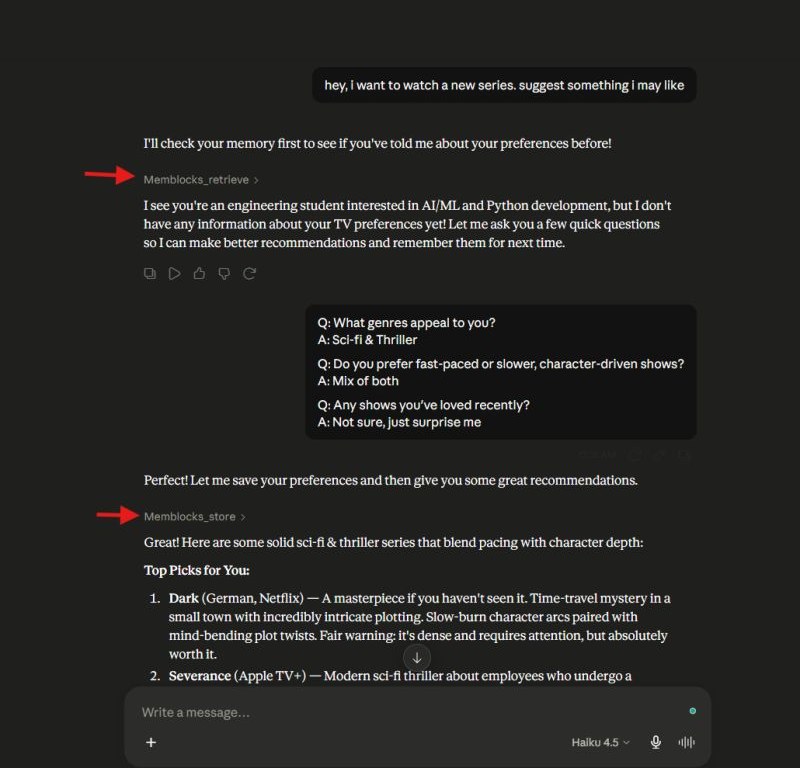
We built an MCP server around the library to demonstrate how MemBlocks works across heterogeneous AI clients. Different models and platforms like Claude, Opencode, etc. can all read from and write to the same locally stored memory pool. Memory becomes model-agnostic, interoperable and fully private.
Results
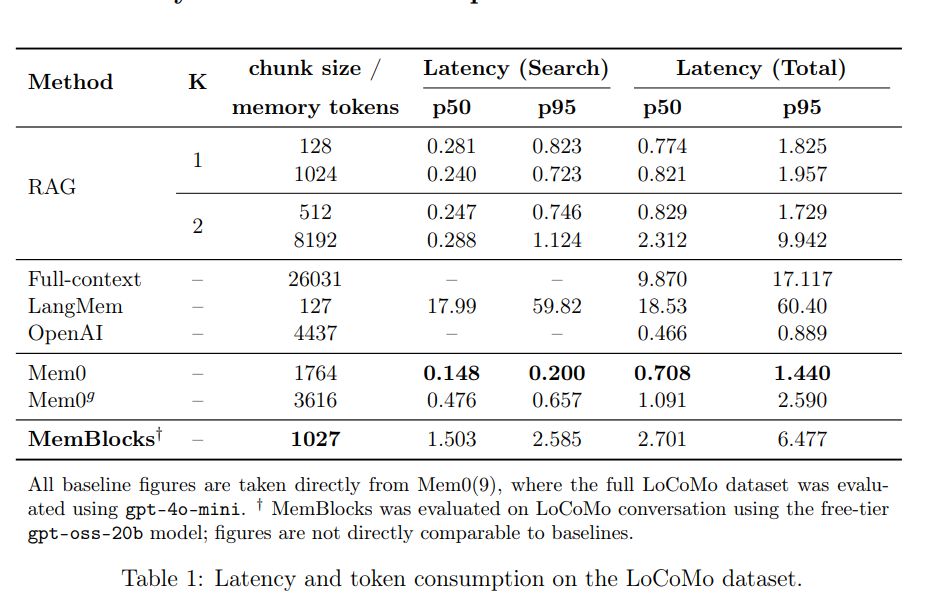
On the LoCoMo benchmark, MemBlocks used 1,027 memory tokens per query, lower than Mem0 (1,764), Mem0g (3,616) and OpenAI Memory (4,437).
It’s still a work in progress. Check it out on GitHub, or pip install memblocks.
Co-built with Aayush Ojha and Ashish Pandey.