demo coming soon
memBlocks
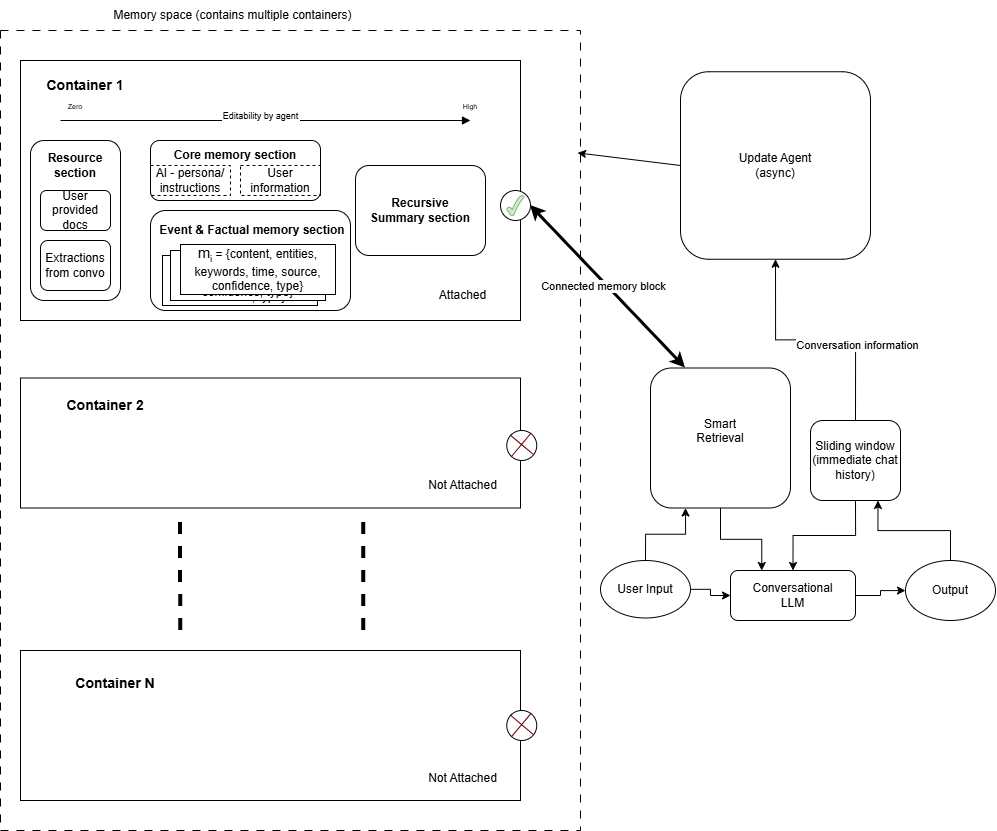
A modular memory library for LLM apps. Memory lives in attachable blocks, each with core facts, hybrid-searched semantic memory and a rolling summary, plus an MCP server and a LoCoMo eval harness.
Python LLM memory Qdrant MCP FastAPI
› notes
- Three memory sections per block: core memory (persona and user facts, always injected), semantic memory (extracted facts, searched with dense + SPLADE vectors in Qdrant and fused with RRF), and a recursively compressed conversation summary.
- Background updates: when the message window fills, core extraction, semantic extraction with ADD/UPDATE/DELETE/NOOP conflict resolution, and summary regeneration run in parallel.
- Ways in: a Python library, a FastAPI + React demo app, and an MCP server so assistants such as Claude Desktop can use a block.
- Eval: a LoCoMo benchmark harness. The upstream README reports 1,027 memory tokens per query, against 1,764 for Mem0 and 26,031 for full context.